

Summarize this article with
If you’re responsible for privacy program operations, you’ve probably asked this question: “Where, exactly, does our personal data live?” It’s the cornerstone of many privacy operations – data mapping, discovery, and classification. But while the industry likes to talk about “data mapping,” the truth is that much of the data you need to map lives outside your walls.
Internal systems—your MySQL, your Snowflake—are already a handful. But at least you own them. You’ve got the keys, the access, the control. Third-party SaaS applications? That’s a different beast entirely.
Modern growth teams are shipping personal data out to platforms like Segment, LinkedIn, Google Analytics, Amplitude, and Facebook every day—for advertising, analytics, personalization, and more. These aren’t *really* your systems. You don’t own them. And they weren’t built with your privacy team’s visibility in mind.
Four ways to uncover personal data in third-party apps
So how do you discover and classify the data stored in these third-party tools? There are four reliable techniques. None of them is perfect on its own. But together, they give you a workable picture—and more importantly, a way to act.
1. The profile or context API (if you're lucky)
When direct access is possible
Some third-party vendors offer an API that lets you request all data tied to a particular user ID. The mParticle Profile API is a good example. With the right API key and identifier, you can hit their endpoint and receive back a JSON payload with everything mParticle has stored about that user—traits, events, metadata. It’s structured, direct, and refreshingly transparent.
This approach gives you clear insight into the specific personal data types being collected and stored—without having to guess. And it can be automated across sample sets to establish data classification patterns within the app.
The problem? Most vendors don't offer this
mParticle built this API because it built a user-centric product. But many platforms don’t follow that pattern. In fact, some applications don’t even allow internal querying of profile-level data, let alone expose that functionality externally.
In other words: when this method is available, use it. But don’t expect it to be common.
2. Watching data leave the browser (where the truth slips out)
What’s flowing out of your digital front door?
If the API route is a front-door approach, this one is more like peeking through the windows.
When users visit your website, their actions trigger a flood of data collection—some of it stored, some of it sent. And a surprising amount of it heads straight into third-party marketing and analytics platforms.
Common third-party destinations include:
- Google Analytics (behavioral analytics)
- LinkedIn (audience segmentation for B2B)
- Facebook (ad campaign personalization)
Why cookies aren't enough
Most privacy teams rely on cookie scanners to understand web data collection, but cookies only tell you what’s being stored in the browser. They don’t expose what’s actively being transmitted out to third parties. And that’s where the more sensitive or identifying data is often hiding.
The action is in the network requests—what’s being sent from your site to vendors in real time. This includes names, emails, IPs, behavioral events, and more.
The technical solution
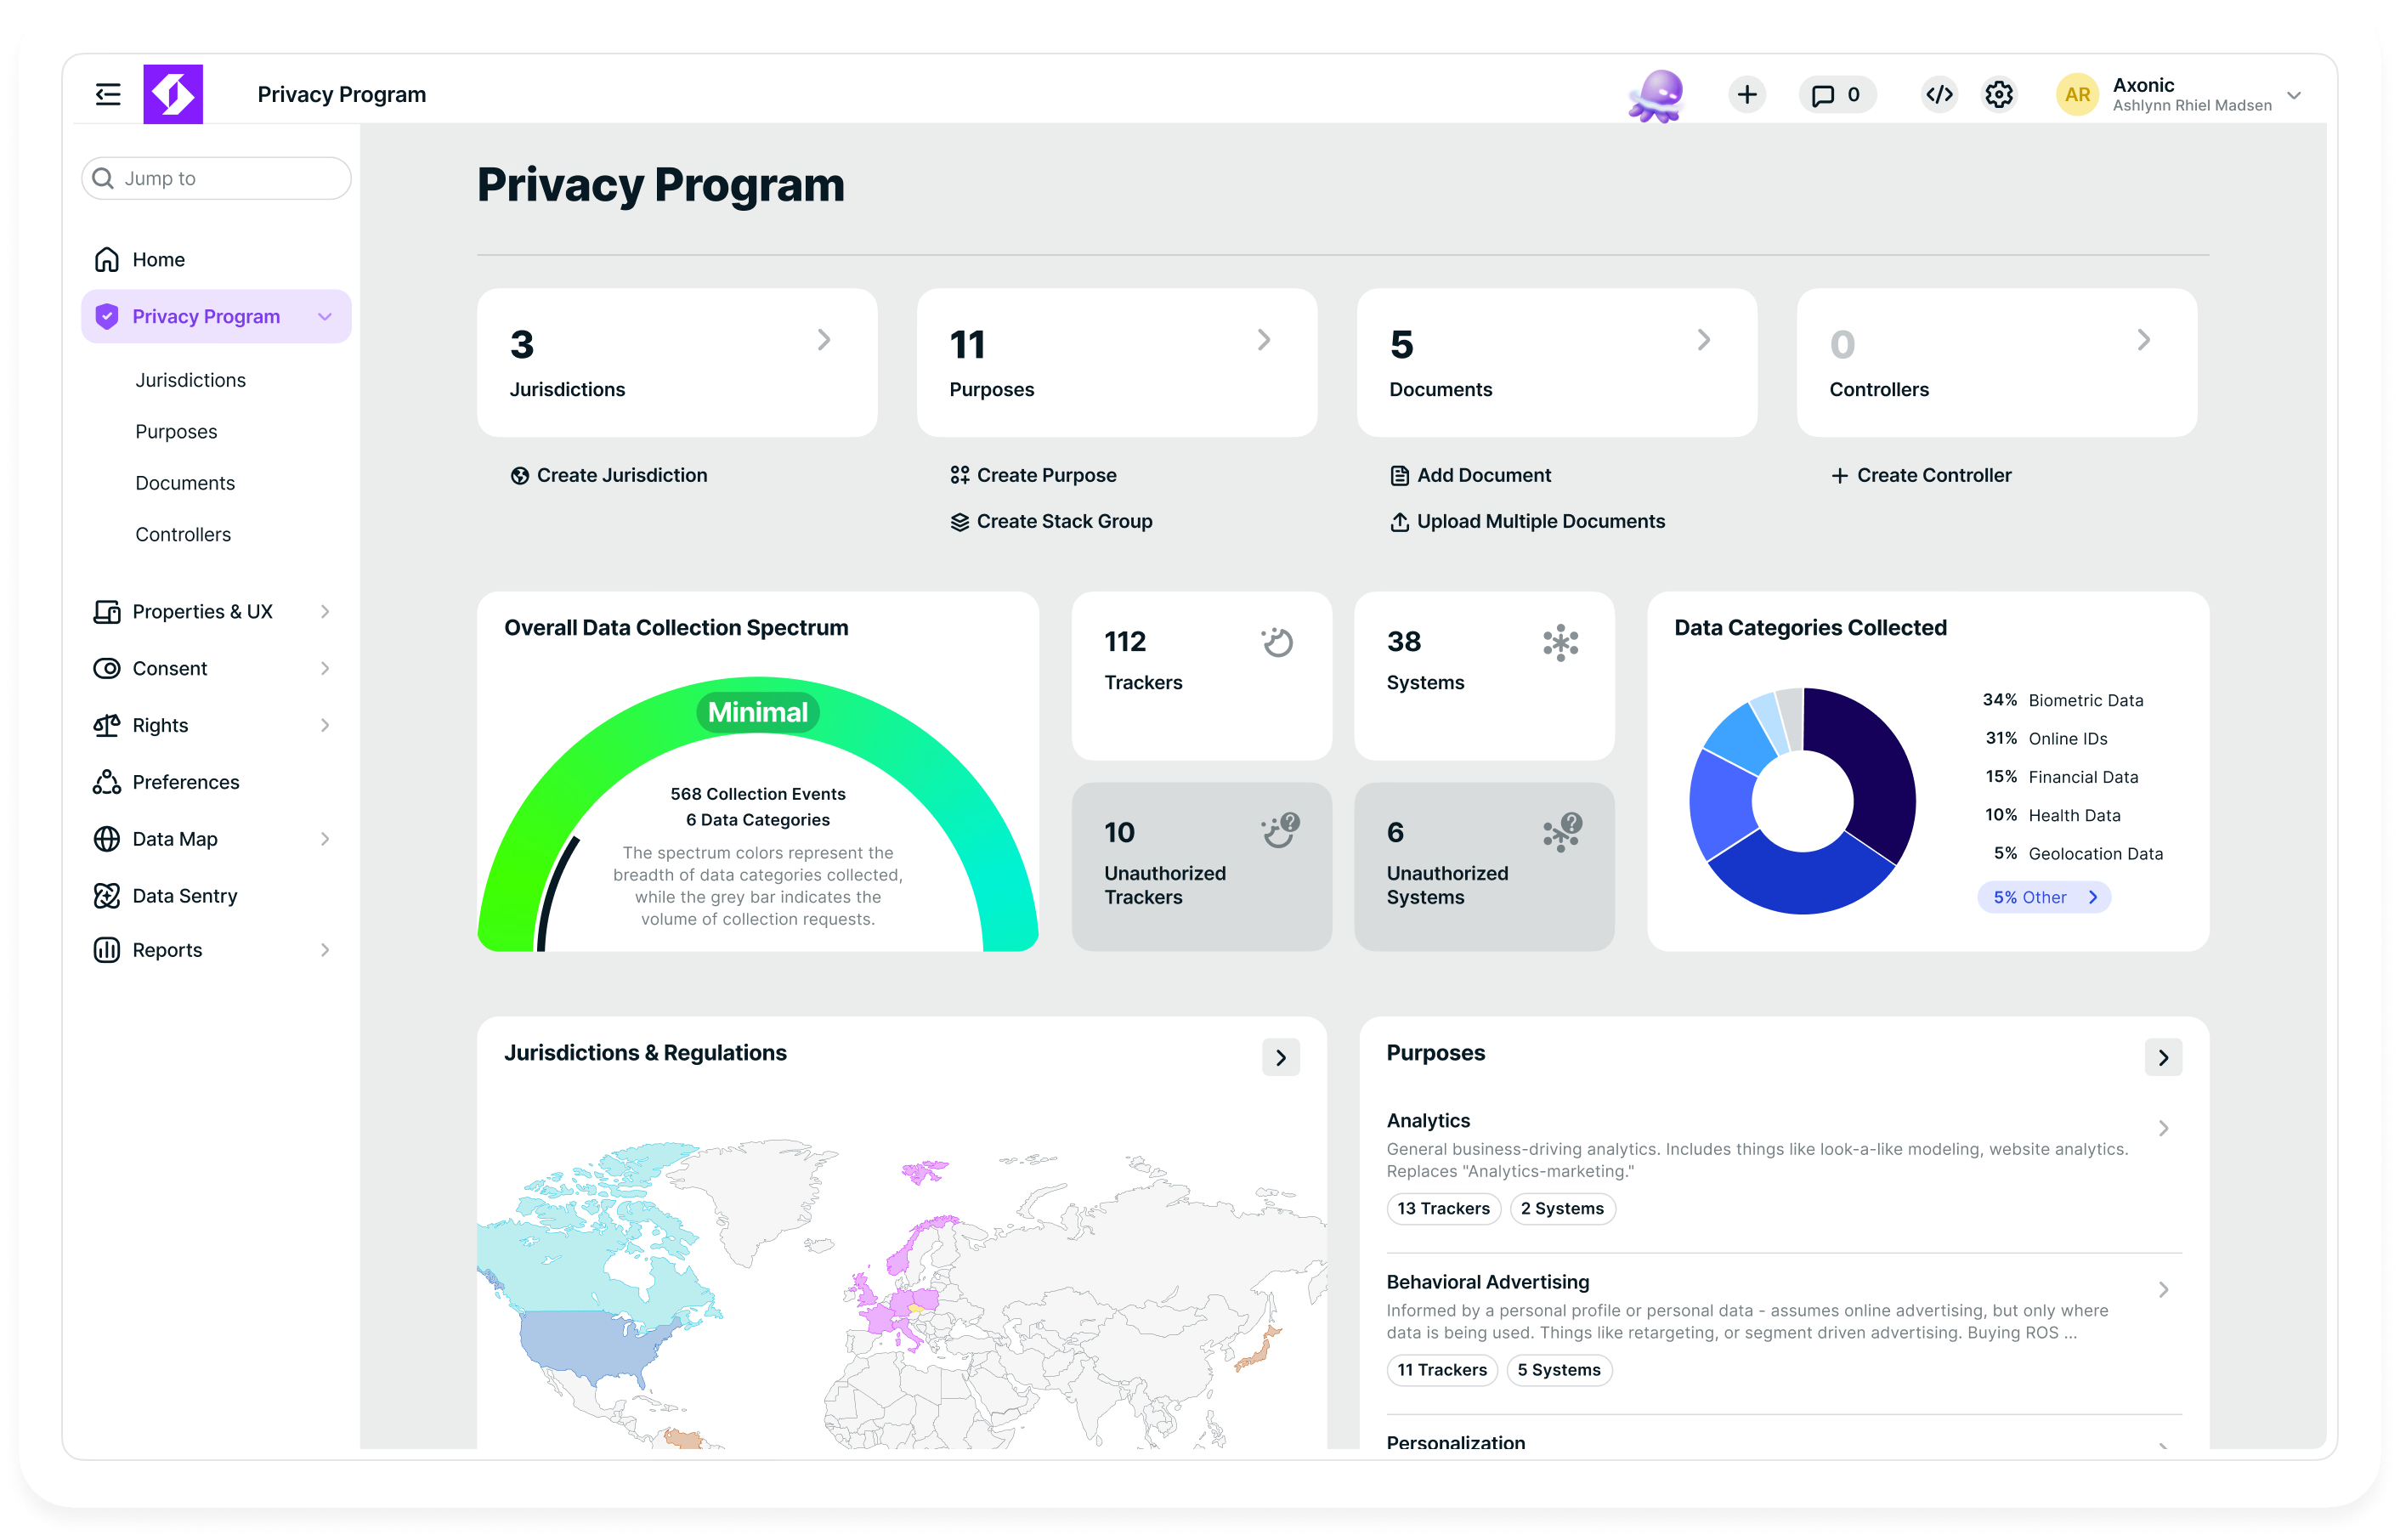
That’s where tools like Ketch Data Sentrycome in. They monitor outbound network traffic, letting you inspect and catalog the personal data leaving your site. This is particularly valuable for uncovering what's being passed to black-box systems like Google Analytics or Facebook Ads—platforms that don’t exactly roll out the red carpet for privacy teams.
3. Synthetic DSARs (yes, you can just ask)
Leverage access rights for discovery
Data Subject Access Requests (DSARs) are meant to give individuals transparency into what data companies hold on them. But privacy teams can co-opt this mechanism to perform controlled, synthetic requests—essentially asking vendors, “What do you have on this (fake) user?”
You create a test profile, run it through the workflows your real users would experience (signups, purchases, marketing flows), and then file a DSAR to the third-party app asking for an export of that data.
Why synthetic DSARs are useful:
- Reveal exactly what data a vendor stores for a test identity
- Work within standard compliance workflows
- Require no deep technical integration
Caveats:
- Depend on vendor support and response quality
- Can vary in completeness or format
When to use this method
This method is particularly useful when API access is unavailable and browser monitoring can’t see what happens once data reaches the third party. DSARs are a legitimate, rights-based approach—meaning you’re using existing legal structures to gain visibility.
That said, response times and data quality vary, so this is best used as a complementary technique, not a standalone solution.

4. The library approach (reading between the contracts)
When all else fails, look to publicly available information
When APIs aren’t available, browser monitoring isn’t practical, and DSARs don’t yield much, there’s still one more way in: external signals.
Think of this as data archaeology. Ketch’s “Library” approach involves scanning vendor contracts, public documentation, and community content to infer what personal data a given system is likely to hold.
We scan for clues in:
- Vendor contracts and data processing agreements
- Product documentation and help centers
- Community blogs and user forums (e.g., Marketo’s community blog)
Turning speculation into evidence
Many vendors and their customers talk openly—if unintentionally—about the kinds of data being ingested and processed. A help doc might explain how to “pass user location and device type into Amplitude,” or a blog post might describe building ad audiences in Marketo based on purchase history.
These data breadcrumbs, when aggregated and analyzed by AI, create a working model of what the system likely contains. It’s the least invasive approach, and often the only viable path when the system in question is opaque or legacy-bound.
No single method, but a complete toolkit
Here’s the blunt truth: you’ll never get a single pane of glass for third-party data discovery. These systems weren’t built for you. They weren’t designed with your privacy obligations in mind.
But by combining these four approaches—Profile APIs, network monitoring, synthetic DSARs, and external documentation analysis—you can build a reliable, evolving map of what’s where.
That’s not just a compliance win. It’s the foundation for:
- Making smarter internal asks, and sounding sharper when you speak with internal stakeholders and system access and discovery
- Pushing back on unclear data flows and suspicions about hidden data risks
- Evaluating privacy tech vendors and data discovery products with all the right discerning questions
You may not control the systems, but you can still uncover what they’re doing. Discovery isn't about perfection—it’s about building enough insight to act with confidence.


